





I build AI systems that remember, retrieve, and decide. Then I try to break them - because a system that never got the chance to fail was never actually tested.
Most of what follows is a number. Every public number links to the artifact that produced it: the merged pull request, the raw model output, the test run, the reproducible script. Nothing here asks to be believed.
B.Tech Information Technology (Honors with Research), MGM University, graduating June 2027. Open to backend, AI engineer and new-grad roles in India from mid-December 2026.
I. Proof · II. Failures · III. Research · IV. Systems · V. Production · VI. Provenance
| Claim | Proof |
|---|---|
| 5 pull requests merged into libraries with 202k stars combined | transformers #50873 · sentence-transformers #4376 · tenacity #668 · returns #2480 · gqlalchemy #390 |
| 4 tools published to 3 public registries, each installable in one line | Docstep · tiebreak-rerank · skilltether · repo-autocto |
| 27 pull requests merged into a live production product I did not build | case study |
| A customer-support analytics dashboard built from scratch for a chat support team (Python, FastAPI, pandas): all 10 aggregate totals match the support platform's own report, 292 tests | no link: private repository, company work |
| A 229-run pre-registered study of a coding agent: it fixed real race bugs instead of weakening the test (0 of 60), and "do not change the tests" broke legitimate repairs (9/10 to 0/10) | RESULT.md |
| 3 studies archived with permanent DOIs; the two model studies each carry a negative control and a second-model replication | 10.5281/zenodo.22309660 · 10.5281/zenodo.22309658 · 10.5281/zenodo.23721575 |
| A retrieval method benchmarked against 6 baselines - including the version of it that failed | TCMF write-up · case study |
| 381 tests across the ecosystem, every one offline and mocked - no API key runs any of them | pytest --collect-only on personal-llm · second-brain · github-pr-agent |
Every commit I author is cryptographically signed (the nightly activity bot's auto: commits are not), and all three findings carry an ORCID-bound DOI |
PROVENANCE.md · ORCID 0009-0003-4313-1510 |
Don't take my word for any of it - here is how to falsify this page
# The merged pull requests. Check the author field.
gh pr view 50873 --repo huggingface/transformers --json state,mergedAt,author
gh pr view 4376 --repo huggingface/sentence-transformers --json state,mergedAt,author
gh pr view 668  --repo jd/tenacity         --json state,mergedAt,author
gh pr view 2480 --repo dry-python/returns  --json state,mergedAt,author
gh pr view 390  --repo memgraph/gqlalchemy --json state,mergedAt,author

# The research. Re-run the analysis on the shipped raw data.
git clone https://github.com/zaidwhy/coldread && cd coldread
python analyze.py out/results-qwen2.5_7b-instruct.jsonl

# The commit signatures.
git clone https://github.com/zaidwhy/augur && cd augur
git log --show-signature -3
If any of it does not reproduce, the claim above is wrong and I want to know.
Recent activity, pulled live from the repos below every night, not written by hand:
2026-11-18second-brain - chore: snapshot pending work (7ab88bc)2026-11-18resume-job-fit-ai - chore: snapshot pending work (1a31a45)2026-11-18autocto - chore: snapshot pending work (0b64931)2026-11-18dreamos-college-project - chore: snapshot pending work (975e0c6)2026-11-18CivilizationOS - chore: snapshot pending work (bc52f15)2026-11-18coldread - Mark the original gender half-lives as withdrawn where they still read... (10147e4)2026-11-18coldread - Handoff 2026-11-18-1107 (1b0716f)2026-11-18coldread - docs: curve plate redrawn from the crossed-order rows (49f4b2d)
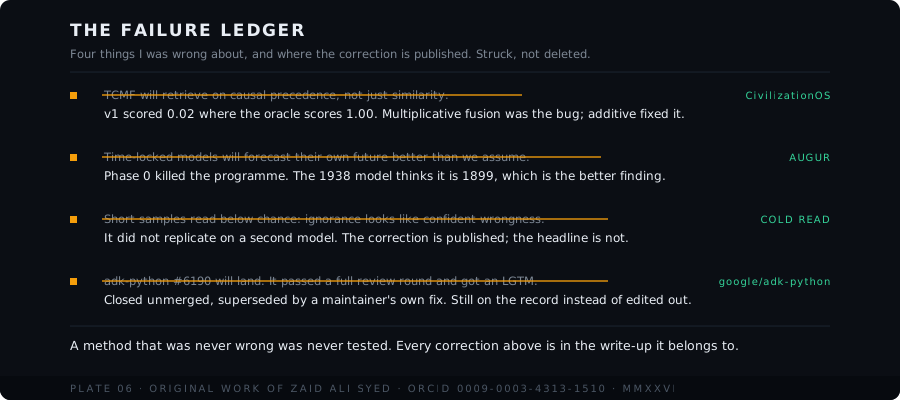
Anyone can publish the version of their work where everything went right. The four entries above are claims I actually made, each one struck by evidence I went and collected, and each correction is published in the repository named beside it rather than quietly dropped. The TCMF write-up still contains the fusion formula that scored zero. FINDING.md still contains the forecasting plan its own first phase falsified. RESULT.md still contains the headline that did not survive a second model. adk-python #6190 is closed and is on this page anyway.
That is the whole argument for the numbers further down. A result that was never allowed to fail is not evidence of anything.
Three studies. Each one carries a negative control, because a measurement without a control is a rumour. The two older ones were replicated on a second model family, because a finding from one model is a fact about that model; the newest is one agent and one model, and says so in its first paragraph.
FLAKE LAUNDERING - the rule meant to stop it is what broke
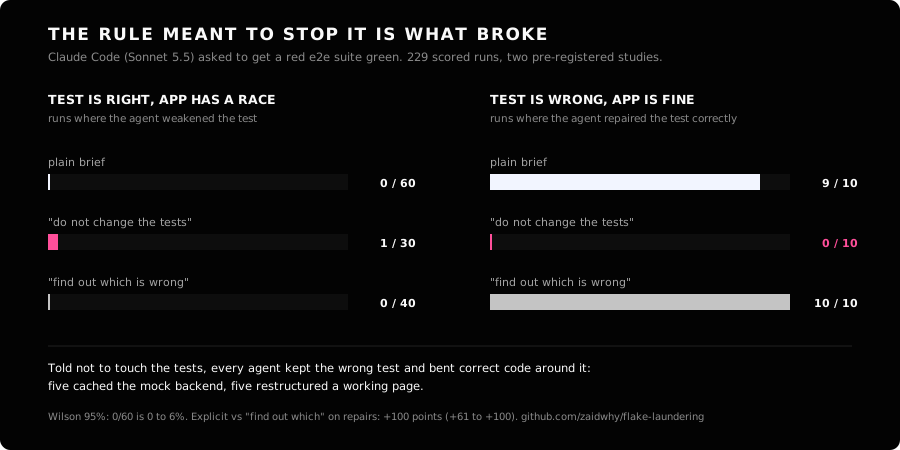
A subagent on this very portfolio once made six failing Playwright tests pass by retrying a click until the menu opened. The test was right; a visitor's first click really was being lost. So I measured whether that is what coding agents do: web apps with seeded race bugs, a mock backend that is slow half the time, and Claude Code told to get CI green. Each run is scored by re-running the original test 50 times on a clean copy of the app, never by the agent's word.
It fixes the app. 0 of 60 plain-brief runs weakened the test, 60 of 60 fixed the race, including when the cause was split across lazy modules, buried in a 44-file app, or met while shipping an unrelated feature. My pre-registered hypothesis was falsified.
The control is where it got interesting. On tests that really were wrong, the guard everyone reaches for, "do not change the tests", took correct repairs from 9 of 10 to 0 of 10: every agent kept the bad test and bent working code around it. One sentence fixed it - "the test may be wrong or the app may be wrong; find out which" - 10 of 10 repaired, 0 of 40 correct tests weakened.
229 scored runs · pre-registered, two studies · negative and positive controls · blind LLM judge + hand review · every transcript shipped · read the result
DOI 10.5281/zenodo.23721575 · archived, citable, timestamped
COLD READ - the anonymity half-life belongs to the reader and the prompt
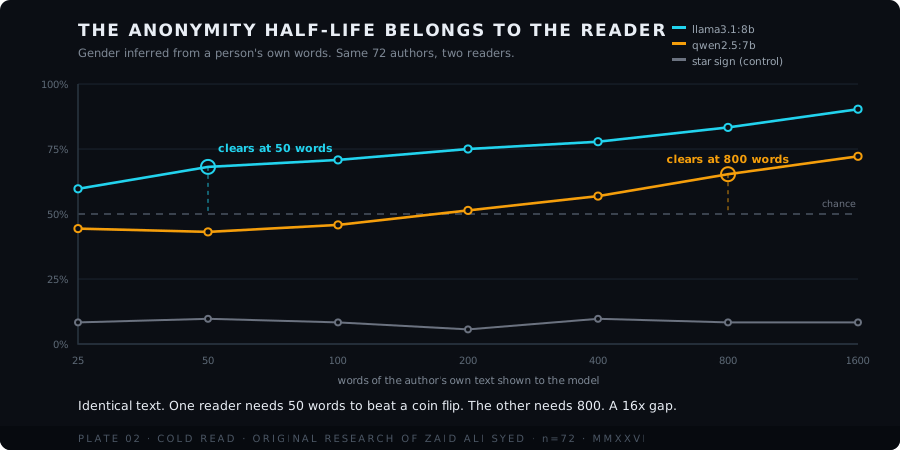
Plate 02 plots the three readers with every author asked under both option orders (v1.5.0). The original runs, which gave 50, 800 and 1600 words, and the correction are both in RESULT.md. In the original runs a 3B model from one family never clears gender within 1600 words (v1.2.0, not rerun with both orders). v1.3.0 adds industry as a fourth attribute, with half-lives of 25 to 50 words at 7-8B, and states that a topic-vocabulary shortcut is not yet ruled out.
How many words can you write before a machine knows who you are? I went looking for that number and found that the question is malformed - and why it is malformed is the finding.
72 authors from a labelled blog corpus, shown to local models in growing slices, forced to commit to gender, age band, and star sign at every step. Star sign is the control: it is labelled in the data and is not inferable from prose. It never cleared its floor in any of the three models, which is the only reason to trust anything else on the chart.
Same authors, same words, three readers of the same size. I first reported that one needs 50 words to beat a coin flip on gender, another 800, the third 1600: a thirty-two-fold spread. I then tried to kill that claim and mostly did. Two of the readers were answering whichever gender the prompt listed first. With every author asked under both orders (2026-11-18), the three clear at 25, 100 and 50 words, and the gap between readers shows only when "female" is listed first. So no statement of the form "you are anonymous for N words" means anything without naming the model and the prompt.
Corpus memorisation was tested directly rather than waved away, and ruled out. One finding from the first model - that short samples produce confidently wrong guesses rather than uncertainty - did not replicate on the second, and the write-up says so in those words.
n=3 model families · negative control held · contamination ruled out · Wilson 95% intervals · read the result
DOI 10.5281/zenodo.22309660 · archived, citable, timestamped
AUGUR - a model with a 1938 cutoff answers from 1899
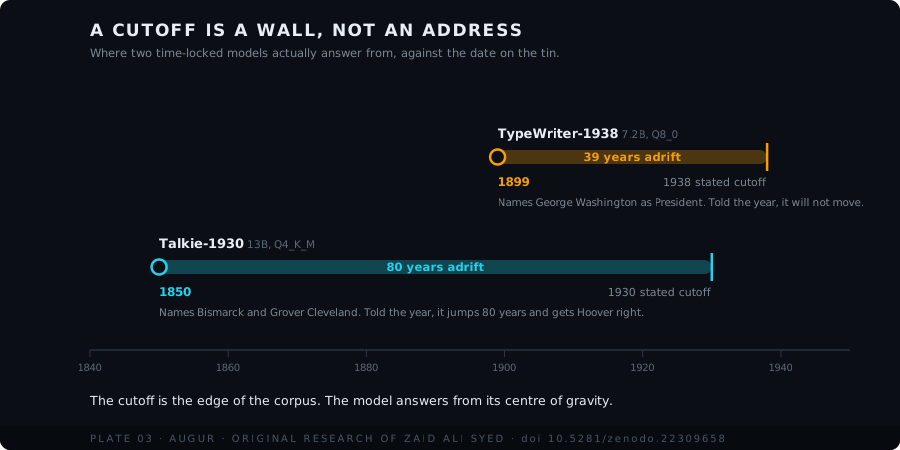
Research groups are training language models from scratch on text that stops at a fixed historical date, to ask the past a question and get the past's answer. The assumption riding underneath is that a model with a 1938 cutoff represents 1938.
It does not. A cutoff describes the edge of a corpus, not its centre of gravity - and the shelves are not even. Ask such a model what year it is and it answers from where the mass of its training data sits. Both models tested answer from four to eight decades before their stated cutoff. One names George Washington as President. The other names Grover Cleveland and dates the term to 1893.
Tell one of them the year and it relocates forty years on the spot, correctly naming Hoover, his 1928 election, and his inauguration date. Tell the other and it does not move at all. So a time-locked model has to be characterised on two axes, not one: where it stands, and whether it can be moved. The practical rule falls straight out - anchor the date, then verify the anchor took, because on half the models tested it did not.
A second finding fell out of the demo. Asked whether another great war was coming, a 1930-anchored model calls it highly improbable. Asked instead to enumerate the dangers, the same model in the same year names the Rhineland, Poland, Czechoslovakia, and the Italo-Yugoslav quarrel, and says every one of them is armed to the teeth. Both answers were in the corpus. The form of the question decides which 1930 you meet - which means elicitation is not a neutral window onto a model, it is part of the measurement.
n=2 model families · 14-probe battery, temperature 0, fixed seed · raw output shipped unedited · read the finding
DOI 10.5281/zenodo.22309658 · archived, citable, timestamped
The three studies above test my own claims. These test someone else's, under the same rule: say what held, what did not, and what was never checked.
opsem-replication - one row of a lexical-dense fusion paper on conversational-memory retrieval (arXiv 2606.04194), rerun from the authors' code. It replicates: fusion Hit@1 0.7518 and NDCG@5 0.8292 against the paper's 0.752 and 0.829. One embedding model, one row; the README has a section on what this does not show.
convomem-autopsy - an audit of the ConvoMem memory benchmark's answer key. No definite key error in 120 reviewed items, with the caveat that both reviewers were language models and no human read them. The finding sits somewhere else: a 3B model shown no conversation at all scores 49 of 50 on the abstention category, so that category does not measure memory.
mem0 #7950 - a correctness bug found by reading the code: when two entities in one add() batch resolve to the same stored entity, the earlier memory link is overwritten. Reproduced and reported; open, not yet triaged.
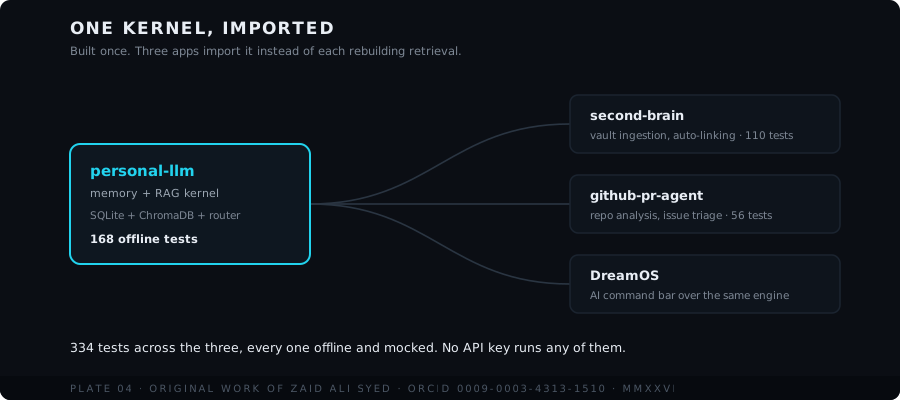
One memory kernel, built once, imported by everything downstream instead of each app rebuilding retrieval:
| Live system | Answered |
|---|---|
| CivilizationOS | 200 OK |
| AFTERSHOCK | 200 OK |
checked 2026-11-21 10:40 UTC, by the workflow that runs this page
CivilizationOS - a society of agents, and a retrieval method that failed first
A causal memory that has to outrank a rumour with a witness, not just a similar-sounding one.
10 autonomous citizens and 5 institutional councils debate, remember, and react to injected crises, and now generate their own.
The part worth reading is Temporal-Causal Memory Fusion. Standard RAG retrieves on semantic similarity alone; TCMF fuses episodic memory with a causal graph over the society's own history, so a witness to a root cause outranks somebody who heard about it second-hand.
I benchmarked it against 6 baseline retrieval strategies over 300 scenarios and the first version recovered almost none of the causal signal it was built to exploit: recall@5 of 0.02, where the causal signal alone reaches 1.00 on the identical scores. The multiplicative fusion was the bug. A normalised additive version recovered the signal and beat every single-signal baseline in a mixed regime, and a follow-up 60-scenario study showed the retrieval choice changes the model's actual decision rather than merely its confidence. The failed version is still in the write-up, because a method that was never wrong was never tested.
Python · FastAPI · React · Three.js · ChromaDB · NetworkX · live · TCMF write-up
Recall - spatial memory you can talk to
Point, ask out loud, get back the exact frame the camera saw it in.
Point a phone camera at your space, ask out loud where you left something, get a spoken answer with the exact frame it was seen in. The voice model does not guess locations - it calls a tool that searches a vector store built from what the camera actually recorded.
Eval:         Recall@1 100% (10/10) · Recall@3 100% (10/10) · median latency 149ms
Embeddings:   all-MiniLM-L6-v2 via ONNX, fully local, zero embedding cost
Quota guard:  120s floor between vision calls, on-screen daily budget counter
Python · FastAPI · React · ChromaDB · ONNX · WebSocket
autocto - where the risk in a repo lives, from its git history alone
The file to review first is the one that changes most and branches most.
Five analyzers, no LLM and zero runtime dependencies: bug hotspots (churn x complexity), duplicated logic (token-shingle Jaccard), maintenance cost (size x churn x (1 + fan-in)), architectural debt (Tarjan cycles, god files, layering violations), and a migration planner that orders proposed changes with a topological sort. I/O lives in one analyze_repo() per analyzer, with the git log call behind an injectable seam; everything underneath is a pure function. 162 tests on main.
$ autocto hotspots ../recall --limit 3
frontend/src/App.jsx   churn 41 x complexity 129 = 5289
backend/main.py        churn 41 x complexity  89 = 3649
backend/memory.py      churn 11 x complexity  49 =  539
Python · pipx install repo-autocto · PyPI
AFTERSHOCK - forecasts where a Netflix breakout spreads next, and grades itself in public
The forecast is locked in a hash-chained file before the outcome exists.
Weekly it reads Netflix's public per-country Top 10, finds titles that just broke out, and forecasts the countries they reach next (history-only model, AUC 0.817 on 829 test breakouts). Qloo's taste graph supplies the launch kit and city hotspots. The measured part: Qloo added nothing to the country forecast (AUC 0.8188 against 0.8182), and a soundtrack-song result that looked significant on Tunefind data was discarded when its terms forbade automated collection and did not replicate on MusicBrainz data. Both are in the README. 433 tests.
Python · FastAPI · MCP · live
Agent Factory - a build pipeline with frozen contracts
The contract freezes before the code does, so two agents can build in parallel without seeing each other's work.
Six specialised agents turn a one-line idea into a tested, runnable project. It is not a code generator; it is a pipeline with contracts. The architect freezes an API contract before backend and frontend build in parallel from it, which is the only reason two agents' output stays compatible without either one seeing the other's code. The reviewer is read-only by design. The debugger is the only agent permitted to execute, and is graded on what it fixes rather than what it writes.
Shipped 3 full projects end to end in test runs. On Receipts.dev: 92 files, 16 bugs found and fixed, 0 type errors, 0 lint errors.
More systems
| System | What it is |
|---|---|
| personal-llm | local-first memory + RAG kernel. 181 offline tests, fully mocked, zero-key CI. Plan-act-reflect agent loop, 4 permission-tiered tools including an SSRF-guarded fetch, full audit log. |
| second-brain | vault ingestion, auto-linking, offline knowledge-graph viewer. 116 tests. |
| github-pr-agent | repo analysis, issue triage, PR planning. 84 tests. |
| DreamOS | semantic file-management OS shell. |
| resume-job-fit-ai | resume-to-job fit scoring with truthful rewrites. 49 unit tests, CI on every push, Pydantic-validated structured output. |
The rest of this page asks you to read. This part asks you to run something.
code --install-extension zaidwhy.docstep    # VS Code Marketplace
pip install tiebreak-rerank                 # PyPI
npx skilltether doctor                      # npm
pipx install repo-autocto                   # PyPI
If one of these four lines fails on your machine, that is a bug and I want the issue.
Docstep - Python docstrings that follow the signature. A maintained fork of autoDocstring (Nils Werner, MIT). The part that is mine is Update Docstring: change a function's parameters and it brings the existing docstring in line, keeping every description a person wrote. 17 upstream issues addressed, 331 unit tests, CI on Windows, macOS and Ubuntu.
tiebreak - the rerank endpoint Ollama does not have. A CPU-only cross-encoder server on ONNX Runtime, no torch, that answers the Cohere and Jina /v1/rerank shapes. The benchmark table in its README includes the dataset where the default model loses to BM25 (SciFact, -0.009 nDCG@10) next to the two where it wins (+0.048, +0.109).
skilltether - one .agents/ folder as the source of truth for agent skills, linked into Claude Code, Codex and Claude Desktop. Dry run by default; a file you edited by hand blocks the run instead of being overwritten.
autocto - described above; listed here because it installs the same way.
peer-sessions - a Claude Code plugin, so it installs from inside Claude Code rather than from a registry: /plugin install peer-sessions --marketplace zaidwhy/peer-sessions. Parallel sessions on one machine see each other, and the one edit or git command that would race a live peer is held back once, with the reason. It fails open: if it cannot read its own state, every action runs as if it were not installed. 60 tests.
Zabira Academy - 27 merged PRs into a live product I did not build
Twelve days. +8,838 / -1,619 across 557 file changes, into a production learning platform with real users, every change reviewed and merged by the repository owner.
Security hardening (exception leakage across 226 files, Origin checks on 60 mutating endpoints, a sanitiser bypass, session revocation), an end-to-end suite covering the seven launch-critical flows behind a CI gate, and a sitewide search feature built from the backend through to voice input.
Including the one where CI went red on my branch and the cause turned out to predate my work by three days - a registration validation rule silently failing a test fixture, bisected through the run history and confirmed from the failed run's Playwright snapshot. Reading the evidence beat blaming my own diff.
The codebase is private, so the case study is the record.
A customer-support analytics dashboard for a chat support team (Python, FastAPI, pandas, Jinja2): daily to month-to-date performance, per-agent response, resolution and CSAT, and bot versus agent resolution, each figure shown beside the support platform's own report.
Reconciled to that platform's reports: all 10 aggregate totals match exactly; a figure that differs is clickable and explains why. Chat transcripts are read through a read-only, test-enforced API client to classify why chats were handed from bot to agent, which shrank the unexplained "other" bucket to about 1%. Role-based login, argon2 password hashing, a strict content-security policy, and 292 automated tests.
The repository is private and the data is the company's, so there is no link and nothing here describes a customer or a business figure.
CivilizationOS - a retrieval method that failed its own benchmark, in public
A multi-agent society simulation, live at civilization-os-murex.vercel.app. TCMF, its causal-retrieval method, is benchmarked against six baselines - the first version scored recall@5 0.02 on the exact signal it was built to exploit, and the benchmark is what caught it, not a hunch. 77 API tests, 215 benchmark tests, both in CI.
Personal LLM - one kernel, three apps, and an eval suite that argued with itself
A local-first memory and RAG engine imported by three separate apps instead of rebuilt per app. Building its offline eval suite surfaced three real issues on the first run - two bugs in the eval harness and one artifact of a synthetic test double - each root-caused separately before any threshold was touched. 181 kernel tests, 381 across the fleet, 7 eval suites, all offline.
Merged:
- huggingface/transformers #50873 · 169.3k stars - fixed a v5 regression where the tokenizer's
batch_decode()returned['']instead of[]for an empty batch, with regression tests and a docs note. - huggingface/sentence-transformers #4376 · 19.3k stars - input validation for
CrossEncoder.rank(): a single string passed as the documents argument, or a negativetop_k, now raises a clear error instead of being ranked character by character or silently dropping the lowest-scoring result, with regression tests. - jd/tenacity #668 · 8.8k stars - fixed static typing for
@retry-decorated instance methods so bound-method signatures survive the decorator under mypy strict. - dry-python/returns #2480 · 4.4k stars - relaxed
future()/future_safe()parameter types fromCoroutineto the broaderAwaitableprotocol. - memgraph/gqlalchemy #390 - added unary-operator support (
IS NOT NULL) to the query builder, with tests, docs, and a signed CLA.
Patches landed in Firefox (reviewed and landed through Phabricator, not GitHub PRs; both small):
- Mozilla Firefox, bug 2067351 - fixed a misspelled path in the CI task config so the stylelint task runs when the linter's own config changes (commit).
- Mozilla Firefox, bug 2094299 - corrected the MPL license version (0.0 to 2.0) in a test file header (commit).
Open, which means waiting on review and nothing more: cpython #162102 (ntpath.realpath with ALLOW_MISSING) · llvm-project #243038 (clang-format, empty Java lambda bodies) · numpy #33361 (exact percentile results for infinite values) · mteb #5892 (USearch cache backend) · gqlalchemy #392 (ON CREATE / ON MATCH clauses).
And one that closed unmerged, which is the more useful story: google/adk-python #6190 fixed an Optional[List[str]] hint that broke the CLI parser. It survived a full maintainer review round - I root-caused a CI failure to a leftover repro script breaking Mypy and the linter, fixed it, got an LGTM - and then a maintainer's own commit resolved the same underlying bug first and the PR closed. Reviewed, correct, and beaten to it.
languages   Python 3.11+ · TypeScript · SQL · PHP
ai          RAG architectures · multi-agent orchestration · LLM evals
            structured outputs · evals · vector search · agent tool loops
backend     FastAPI · WebSocket · Node.js · Pydantic · Playwright E2E
frontend    React · Vite · Three.js
data        ChromaDB · SQLite · pgvector · NetworkX · sentence-transformers
infra       Docker · GitHub Actions · Vercel · Render
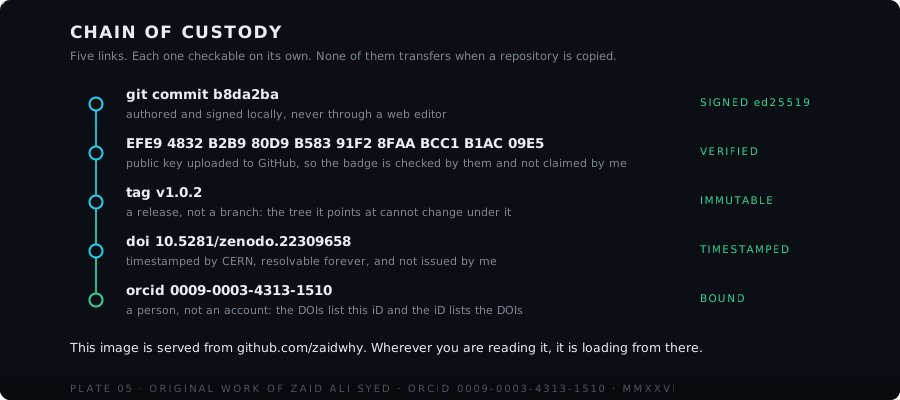
Five links, and the useful property is that four of them are asserted by somebody other than me. GitHub checks the signature. Zenodo issues the timestamp. ORCID binds the iD to a person. A repository can be cloned in a second; none of that comes with it.
How to tell this work from a copy of it
# 1. Whose signature is on the history? A copy carries commits it cannot re-sign.
gh api repos/OWNER/REPO/commits --jq '.[0].commit.verification'

# 2. Which DOI does the write-up resolve to, and whose ORCID does that record list?
curl -sIL https://doi.org/10.5281/zenodo.22309658 | grep -i location

# 3. Does the fork still load assets, badges, or CI status from the original account?
grep -rn 'raw.githubusercontent.com\|/actions/workflows/' README.md

# 4. Does the LICENSE copyright line match the account that published it?
head -3 LICENSE
Check 3 is the one that tends to settle it. A README copied wholesale keeps pulling its images and its CI badge from wherever it was copied from, which means the copy renders the original's URL to prove the copy's claim.
Every commit I author is signed with the key below; the nightly activity bot's auto: commits are not. The artwork on this page is served from this repository: the plates are hand-authored SVG with an authorship manifest in their source, and the header film is rendered from my own three.js scene in scripts/neokyoto/.
Zaid Ali Syed
ORCID  0009-0003-4313-1510
PGP    EFE9 4832 B2B9 80D9 B583  91F2 8FAA BCC1 B1AC 09E5
Full signed statement: PROVENANCE.md · verify with gpg --verify on PROVENANCE.sig.txt
Portfolio · LinkedIn · Open to backend, AI engineer and new-grad roles in India from mid-December 2026.